Digital Humanities @ KU: Report

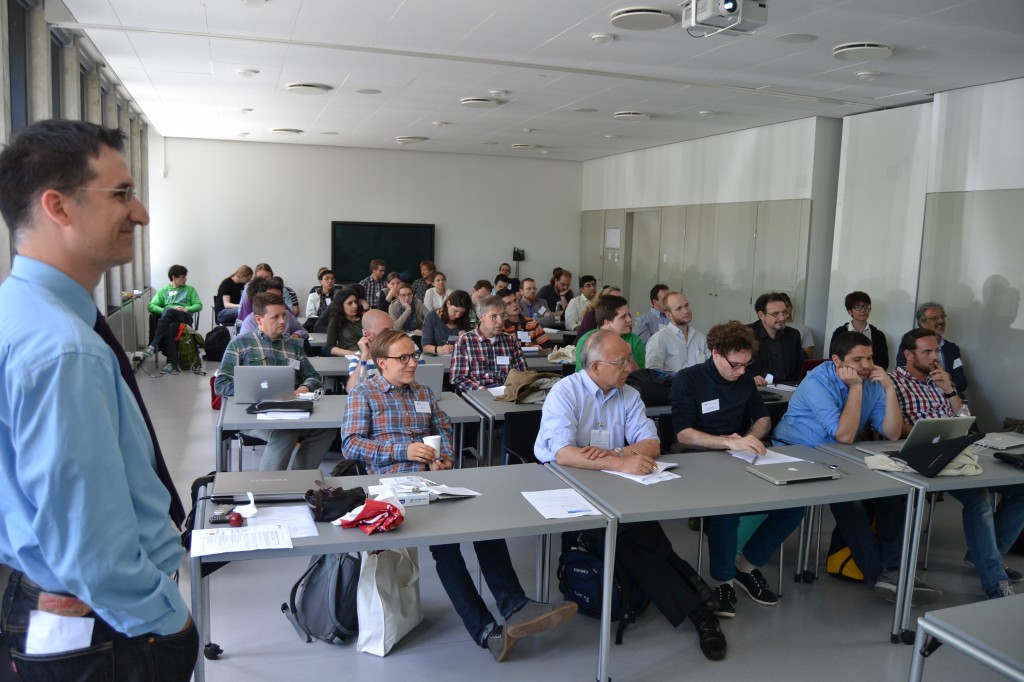
Earlier this month I had the pleasure of being invited to hold a workshop with Isabel Meirelles on complex network visualization and analysis at the Digital Humanities 2014 Forum, held at Kansas University, Lawrence. I figured that this is a good occasion to report on my experience, since it was very interesting and, being quite different from my usual venues, it adds a bit of diversity. The official page of the event is useful to get an overall picture of what was going on. It will be helpful also for everything I will not touch upon in this post.
net_ex19

I think that one of the main highlights of the event was the half of our workshop curated by Isabel, with the additional keynote that she gave. Isabel is extremely skilled both in the know-how and in the know-what about information visualization: she is not only able to create wonderful visualizations, but she also has a powerful critical sense of what works and what doesn’t. I think that the best piece of supporting evidence for this statement is her latest book, which you can find here. As for my part of the workshop, it was focused on a very basic introduction to the simplest metrics of network analysis. You can take a glance at the slides here, but if you are already somewhat proficient in network terminology do not expect your world to be shattered by it.

The other two keynotes were equally fascinating. The first one was from Steven Jones. His talk gravitated around the concept of the eversion of the virtual into reality. Many works of science fiction imagined human beings ending up in some more or less well defined “virtual reality”, where everything is possible as long as you can program it. See for example Gibson’s “Neuromancer”, or “The Matrix”, just to give a popular example that most people would know. But what is happening right now, observes Jones, is exactly the opposite. We see more and more examples of virtual reality elements being introduced, mostly playfully, into reality. Think about qonqr, where team of people have to physically “fight” to keep virtual control of an actual neighborhood. A clever artistic way to depict eversion is also:

The last keynote was from Scott Weingart. Scott is a smart guy and he is particularly interested in studying the history of science. In the (too few!) interactions we had during the forum we touched upon many topics also included in his talk: ethic responsibility of usage of data about people, the influence of the perspective you use to analyze human activities and, a must exchange between a historian of science and yours truly formed as scientist in Pisa, Galileo Galilei. I feel I cannot do justice to his very eloquent and thought-provoking keynote in this narrow space. So I redirect you to its transcript, hosted on Scott’s blog. It’s a good read.

Then, the contributed talks. Among all the papers you can explore from the official forum page, I’d like to focus particularly on two. The first is the Salons project, presented by Melanie Conroy. The idea is to map the cultural exchange happening in Europe during the Enlightenment years. A great role for this exchange was played by Salons, where wealthy people were happy to give intellectuals a place for gathering and discussing. You can find more information on the Salons project page. I liked it because it fits with the idea of knowledge creation and human advancement as a collective process, where an equal contribution is given by both intellect and communication. By basing itself on richly annotated data, projects like these can help us understanding where breakthroughs come from, or to understand that there is no such a thing as a breakthrough, only a progressive interconnection of ideas. Usually, we realize it only after the fact, and that’s why we think it happened all of a sudden.

Another talk I really enjoyed was from Hannah Jacobs. Her talk described a visualization tool to explore the evolution of the concept of “New Woman”, one of the first examples of feminism. I am currently unable to find an online link to the tool. What I liked about it was the seamless way in which different visualizations are used to tell the various points of view on the story. The whole point of information visualization is that when there is too much data to show at the same time, one has to select what to highlight and what to discard. But in this framework, with a wise choice of techniques, one can jump into different magnifying glasses and understand one part of the story of the term “New Woman” at a time.

Many other things were cool, from the usage of the Unity 3D engine to recreate historic view, to the charming visualizations of “Enchanters of Men”. But my time here is up, and I’m left with the hope of being invited also to the 2015 edition of the forum.
The Curious World of Network Mapping

Complex networks can come in different flavors. As you know if you follow this blog, my signature dish is multilayer/multidimensional networks: networks with multiple edge types. One of the most popular types is bipartite networks. In bipartite networks, you have two types of nodes. For example, you can connect users of Netflix to the movies they like. As you can see from this example, in bipartite networks we allow only edges going from one type of nodes to the other. Users connect to movies, but not to other users, and movies can’t like other movies (movies are notoriously mean to each other).

m1

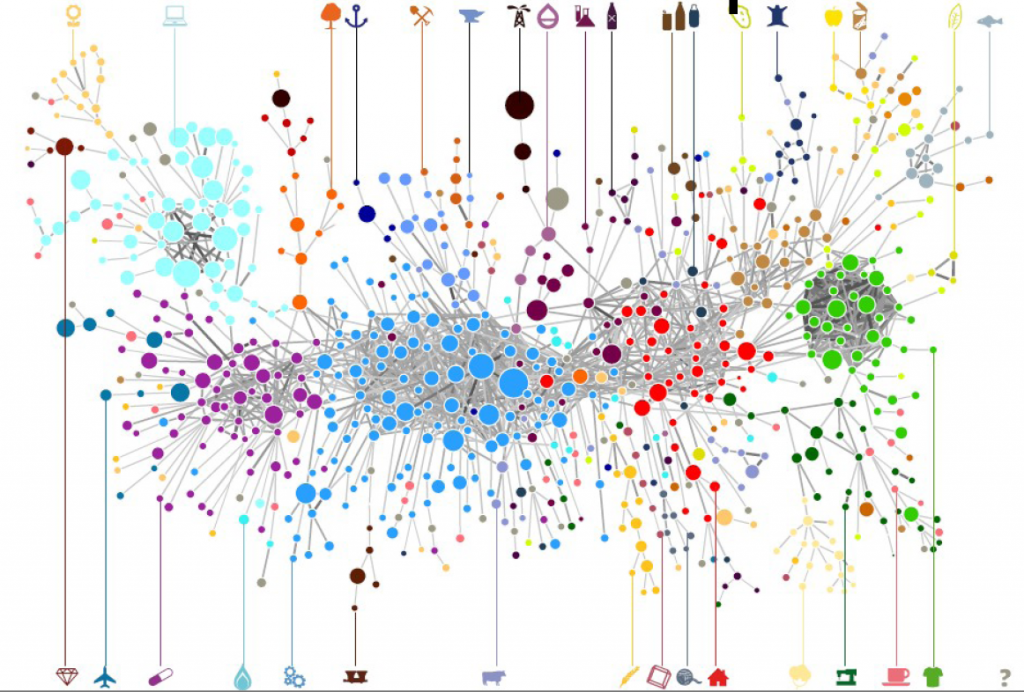
Many things (arguably almost everything) can be represented as a bipartite network. An occupation can be connected to the skills and/or tasks it requires, an aid organization can be connected to the countries and/or the topics into which it is interested, a politician is connected to the bills she sponsored. Any object has attributes. And so it can be represented as an object-attribute bipartite network. However, most of the times you just want to know how similar two nodes of the same type are. For example, given a movie you like, you want to know a similar movie you might like too. This is called link prediction and there are two ways to do this. You could focus on predicting a new user-movie connection, or focus instead on projecting the bipartite network to discover the previously unknown movie-movie connections. The latter is the path I chose, and the result is called “Network Map”.

It is clearly the wrong choice, as the real money lies in tackling the former challenge. But if I wanted to get rich I wouldn’t have chosen a life in academia anyway. The network map, in fact, has several advantages over just predicting the bipartite connections. By creating a network map you can have a systemic view of the similarities between entities. The Product Space, the Diseasome, my work on international aid. These are all examples of network maps, where we go from a bipartite network to a unipartite network that is much easier to understand for humans and to analyze for computers.

ps4

Creating a network map, meaning going from a user-movie bipartite network to a movie-movie unipartite network, is conceptually easy. After all, we are basically dealing with objects with attributes. You just calculate a similarity between these attributes and you are done. There are many similarities you can use: Jaccard, Pearson, Cosine, Euclidean distances… the possibilities are endless. So, are we good? Not quite. In a paper that was recently accepted in PLoS One, Muhammed Yildirim and I showed that real world networks have properties that make the general application of any of these measures quite troublesome.

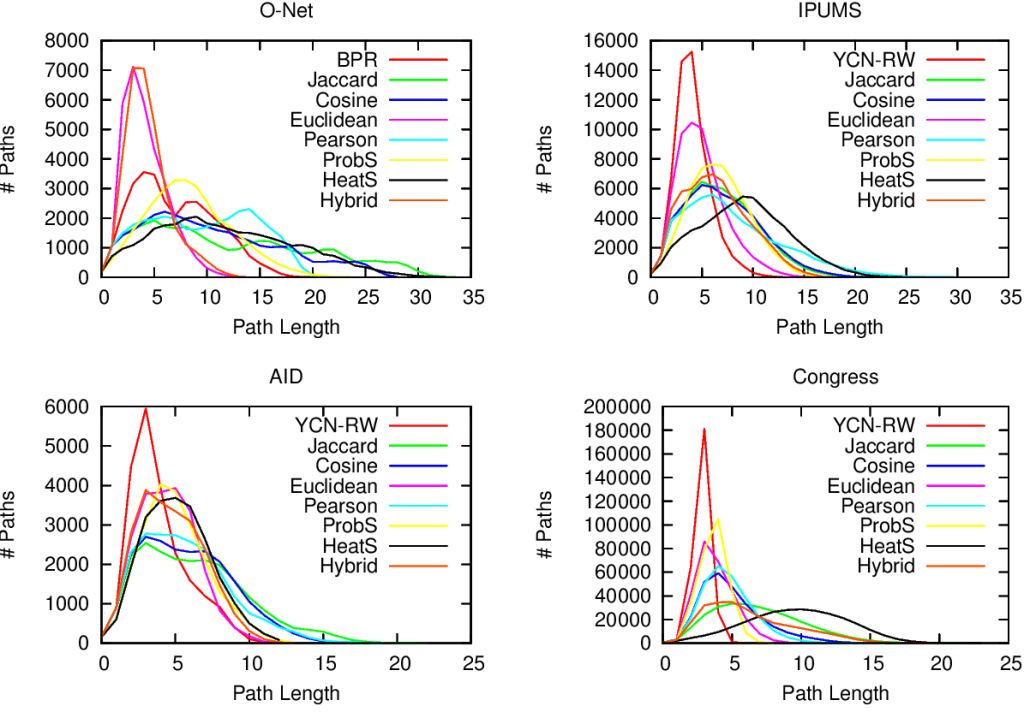
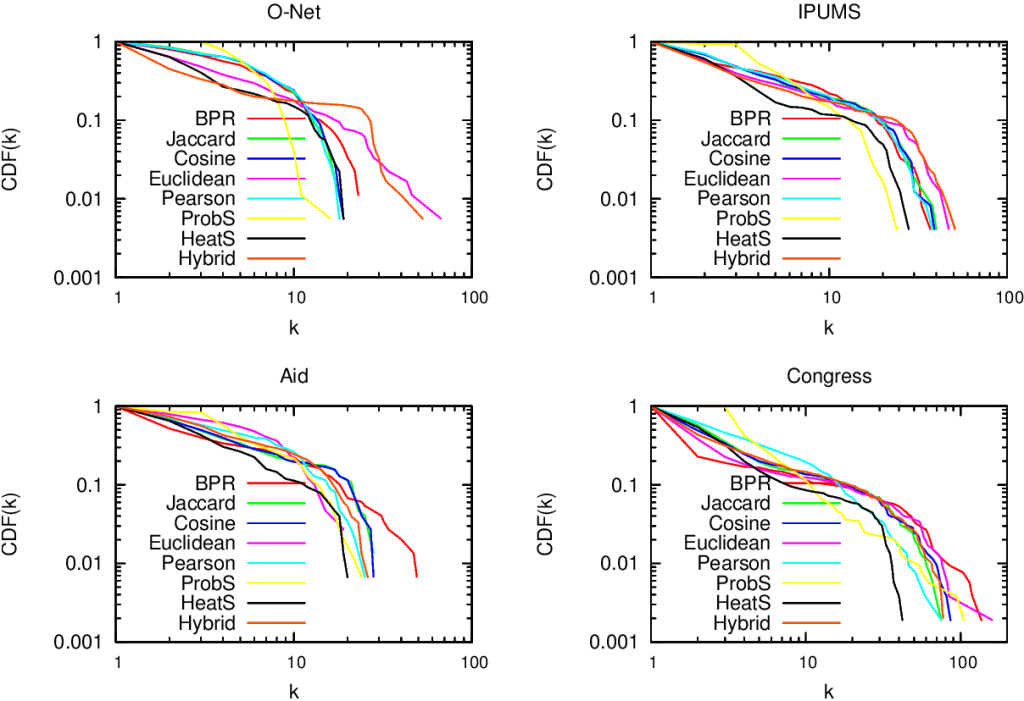
For example, bipartite networks have power-law degree distributions. That means that a handful of attributes are very popular. It also means that most objects have very few attributes. You put the two together and, with almost 100% probability, the many objects with few attributes will have the most popular attributes. This causes a great deal of problems. Most statistical techniques aren’t ready for this scenario. Thus they tend to clutter the network map, because they think that everything is similar to everything else. The resulting network maps are quite useless, made of poorly connected dense areas and lacking properties of real world networks, such as power-law degree distributions and short average path length, as shown in these plots:

m2

m3

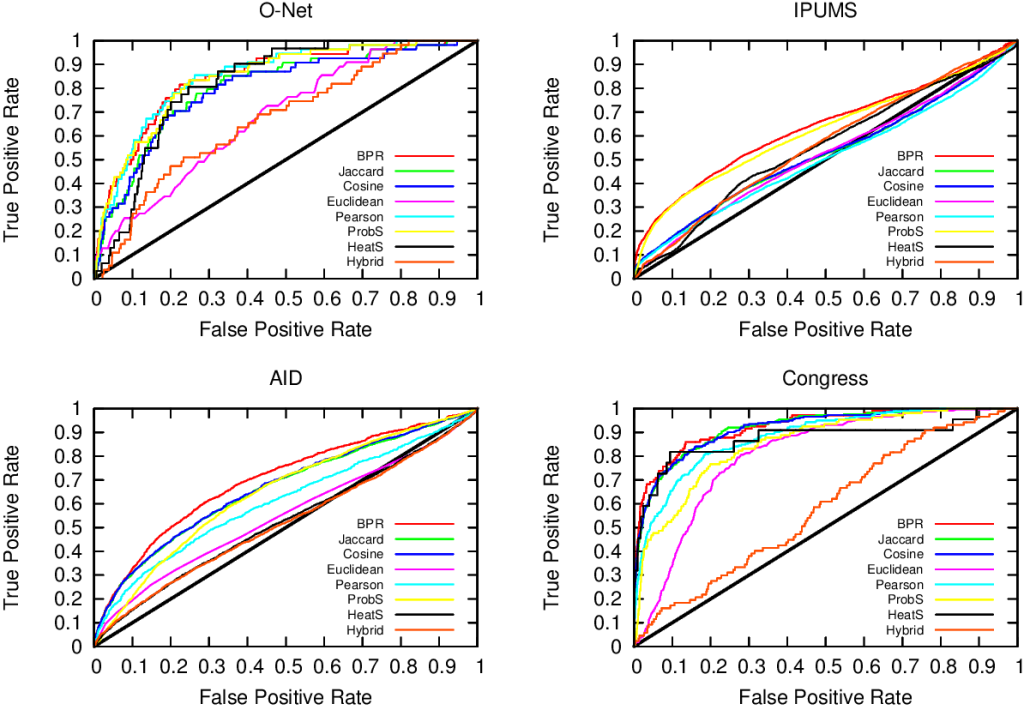
Of course sometimes some measure gets it right. But if you look closely at the pictures above, the only method that consistently give the shortest paths (above, when the peak is on the left we are good) and the broadest degree distributions (below, the rightmost line at the end in the lower-right part of the plot is the best one) is the red line of “BPR”. BPR stands for “Bipartite Projection via Random-walks” and it happens to be the methodology that Muhammed and I invented. BPR is cool not only because its network maps are pretty. It is also achieving higher scores when using the network maps to predict the similarity between objects using ground truth, meaning that it gives the results we expect when we actually already know the answers, that are made artificially invisible to test the methodology. Here we have the ROC plots, where the highest line is the winner:

m4

So what makes BPR so special? It all comes down to the way you discount the popular attributes. BPR does it in a “network intelligent” way. We unleash countless random walkers on the bipartite network. A random walker is just a process that starts from a random object of the network and then it jumps from it to one of its attributes. The target attribute is chosen at random. And then the walker jumps back to an object possessing that attribute, again choosing it at random. And then we go on. At some point, we start from scratch with a new random walk. We note down how many times two objects end up in the same random walk and that’s our similarity measure. Why does it work? Because when the walker jumps back from a very popular attribute, it could essentially go to any object of the network. This simple fact makes the contribution of the very popular attributes quite low.

BPR is just the latest proof that random walks are one of the most powerful tools in network analysis. They solve node ranking, community discovery, link prediction and now also network mapping. Sometimes I think that all of network science is founded on just one algorithm, and that’s random walks. As a final note, I point out that you can create your own network maps using BPR. I put the code online (the page still bears the old algorithm’s name, YCN). That’s because I am a generous coder.

The Eternal Struggle between Partitions and Overlapping Coverages

New year, old topic. I could make a lot of resolutions for this new year, but for sure to stop talking about community discovery is not among them. At least this time I tried to turn it up a notch in the epicness of the title. My aim is to give some substance to one of the many typical filler phrases in science writing. The culprit sentence in this case is “different application scenarios demand different approaches”. Bear with me for a metaphoric example.

When presenting a new toaster, it is difficult to prove that it toasts everything better under any point of view, under any circumstances. It usually does most toasts okay, and for one kind of toasts it really shines. Or its toasts really suck, but it can toast underwater. That’s fine. We are all grown up here, we don’t believe in the fairy tales of the silver bullets any more. At this point, our toaster salesman is forced to say it. “Different application scenarios demand different approaches”. In some cases this is a shameful fig leaf, but in many others it is simply true. Problem is: nobody really checks.

domo_toaster

I decided to check. At least one of them. Teaming up with Diego Pennacchioli and Dino Pedreschi, I put the spotlight on one of the strongest dichotomies in community discovery.  As you may remember, community discovery algorithms can force every node to belong to just one community, or allow them to be in many of them. The former approach is called “graph partitioning”, whilst the latter aims to find an “overlapping coverage”. Are these two strategies yielding interesting, yet completely different, results? This question has been dissected in the paper: “Overlap Versus Partition: Marketing Classification and Customer Profiling in Complex Networks of Products“, that will be presented in one workshop of the 2014 edition of the International Conference of Data Engineering.  Let me refresh your mind about overlaps and partitions.

Above you have the nec plus ultra scenario for a partitioning algorithm. If a partitioning algorithm sees the graph on the left, it would just die of happiness. In the graph, in fact, it appears very clearly that each node belongs to a very specific community. And it can’t belong to any other. If we assume that our algorithm works on edge strength (e.g. the inverse of the edge betweenness), then what the algorithm really sees is the graph on the right. It then proceeds to group together the nodes for which the edge strength is maximal, et voilà.

Here we have an example that’s a bit more complex. The picture has too many overlapping parts, so let me describe the connection pattern. In the graph on the left there are several groups of 6 nodes, each node connected to all other members of the group. In practice, each diagonal is completely connected to the two neighbouring diagonals. Clearly, here there is no way we can put each node in a disjoint group. Why put together nodes 0,1,2 with 3,4,5 and not with 9,10,11? But at that point, why 9,10,11 should be in a community with them and not with 6,7,8? The correct approach is just to allow every completely connected group to be a community, thus letting nodes to be part of more than a community. Some overlapping algorithms see the graph as it has been depicted on the right, with an edge colour per densely connected group.

Time to test which one of these approaches is The Right One! For our data quest we focused on supermarket transactions. We created a network of products that you can buy in supermarkets. To be connected, two products have to be bought together by the same customers in a significant number of times. What does that mean? By pure intuition, bread and water aren’t going to be connected: both of them are bought very frequently, but they have little to do with each other, thus they are expected to be in the same shopping cart by chance. Eggs and flour are too very popular, but probably more than chance, since there are a lot of things you can do with them together. Therefore they are connected. Other specific pairs of products, say bacon flavoured lipstick and liquorice shoelaces, may ended up in the same, quite weird, shopping cart. But we don’t connect them, as their volume of sales is too low (or at least I hope so).

Here are some of the facts we found. First. The overlapping approach* tends to return relatively more communities with a larger amount of nodes than the partition approach**. In absolute terms that’s obvious, since the same node is counted more than once, but here the key term is “relatively”. See the plot above on the right, where we graph the probability (y axis) of finding a community with a given number of nodes (x axis). Second. The overlapping approach returns more “messy” communities. Our messiness measure checks how many different product categories are grouped together on average in the same community. Again, larger communities are expected to be messier, but the messiness measure that we used controls for community size. See the plot on the right, again the probability (y axis) of finding a community with a given entropy (x axis, “entropy” is the fancy scientific term for “messiness”). Third. The partition approach returned denser communities, whose link strength (the number of people buying the products together) is higher.

What is the meaning of all this? In our opinion, the two algorithms are aiming to do something completely different. The partition approach is aiming to create a new marketing classification. It more or less coincides with the established one (thus lower messiness), most customers buy those products together (high link strength) and there are very few giant categories (most communities are small). The overlapping approach, instead, wants to do customer profiling. A customer rarely buys all products of a marketing category (thus increasing its messiness), it has specific needs (that not many people have, thus lowering edge weight) and she usually needs a bunch of stuff (thus larger communities, on average).

Who’s right? That’s the catch: both. The fact that two results are incompatible, in this case, does not mean that one is right and one is wrong. They are just different applications. Which was exactly what I wanted to prove, in this narrow and very specific, probably unsurprising, scenario. Now you should feel better: I gave you a small proof that the hours you spend to choose the perfect toaster for you are really worth your time!


* As overlapping approach, we used the Hierarchical Link Clustering.

** As partitioning approach, we used Infomap.


What is a “Community”?

The four of you who follow this blog regularly will know that I have a thing for something called “community discovery“. That’s because no matter how you call it, it always sounds damn cool. “Discovering Communities” or “Detecting the functional modules” or “Uncovering node clusters”. These are all names given to the task of finding groups of nodes in a network that are very similar to each other. And they make you feel like some kind of wizard. Adding to that, there are countless applications in epidemiology, sociology, immunology, marketing.

Far from being original, I share this passion with at least a thousand researchers. Being as smart as they are, they quickly realized that there are many ways in which you can group nodes based on their similarity. On the one hand, this is good news, as we basically have an algorithm for any possible community you want to find in your network. On the other hand, this made a lot of people freak out, as too many algorithms and too different solutions are usually a big red flag in computer science. A flag that says: “You have no idea what you are doing!” (although a computer scientist would put it in the cold and rational “Your problem is not formally defined”: it means the same).

Yes, my signature "Community Discovery Picture" strikes again!

Yes, my signature “Community Discovery Picture” strikes again!

I personally think that the plus side is more predominant than the minus side, and you can get rid of the latter with a bit of work. Work that I have done with Dino Pedreschi and Fosca Giannotti in our paper “A classification for Community Discovery Methods in Complex Networks“. The trick is very simple. It just consists in noticing what’s wrong with the starting point. “Finding groups of nodes in a network that are very similar to each other”. Exactly what is “similar“? It is an umbrella term that can be interpreted in many different ways. After all, we already do this outside of network science. People can be very similar because they look alike. Or because they like the same things. So why can’t we just have different definitions of communities, based on how we intend similarity?

Well, because at the beginning of community discovery we thought that the problem was well defined. The first definition of community was something like: “A community is a group of nodes that are densely connected, and they have few edges connecting them to nodes outside the community”. Which is fine. In some cases. In others, we discovered that it doesn’t really make sense. For example, we discovered that many social networks have a pervasive overlap. It means that nodes are densely connected with many different groups, disproving the definition: now, the area outside the community could be just as dense as the community itself! And this is just one example: you take a hundred community discovery algorithms in literature and you’ll get a hundred different community results on the same network.

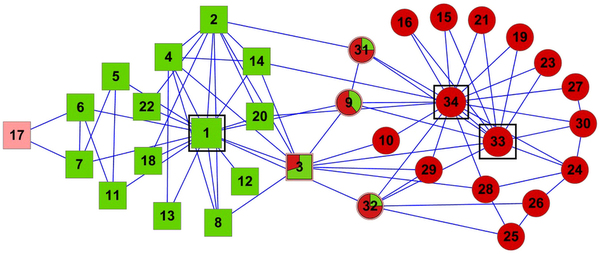
Overlap in the infamous Zachary Karate Club network.

Overlap in the infamous Zachary Karate Club network, you can even win a prize if you mention it!

So now researchers in the community discovery… well… community were divided in three factions. We had those who thought that the problem was ill defined, thus everything done so far was just a royal mess. Then there were those who still thought that the problem was well defined, because their definition of community was the only one standing on solid ground and everybody else was just running around like a headless chicken. And then there were people like me and Sune Lehmann (whom I thank for the useful discussions). Our point was that there were many different definitions of communities, and the incompatible results are just the output of incompatible definitions of community.

This is the main take-away message of the paper. We then moved on and tried to actually spot and categorize all different community definitions (for 90s kids: think of a Pokédex for algorithms). Some choices were easy, some others weren’t. I personally think that more than an established classification, this is just a conversation starter. Also because the boundaries between community definitions are at least as fuzzy as the boundaries between the communities themselves. Algorithms in one category may also satisfy conditions imposed by another category. And to me that’s fine: I don’t really like to put things in separate boxes, I just want to have an insight about them.

I put tags, not classes.

I put tags, not classes.

So here you go, the classification we made includes the following “community types” (names are slightly changed from the paper, but it should be obvious which is which):

  • Common Features: in this definition, each node has a number of attributes. If we are in a social network and the nodes are people, these attributes may well be the social connections, the movies you like, the songs you listen to. Communities are groups of nodes with similar attributes.
  • Internal Density: the classical starting point of community discovery. Here we are interested in just maximizing the number of edges inside the communities.
  • External Sparsity: a subtle variant of the Internal Density class. The focus of this definition is on considering communities as islands of nodes, not necessarily densely connected.
  • Action Communities: this is a very dynamic definition of communities. Nodes are not just static entities, but they perform actions. Again, in a social network you not only like a particular artist: you listen to her songs. If your listening happens with the same, or similar, dynamics of other people, then you might as well form a community with them.
  • Proximal Nodes: here we want the edges inside the communities to make it easy for a node to be connected to all other nodes in the community. Or: to get to any other node in the community I have to follow just a few edges.
  • Fixed Structure: this is a very demanding community definition. It says that the algorithm knows what a community looks like and it just has to find that structure in the network.
  • Link Communities: one of my favorites, because it revolutionizes the idea of community. Here we think that we need to group the edges, not the nodes. In a social network, we know different people for different reasons: family, work, free time, … The reason why you know somebody is the community. And you belong to many of them: to all the communities your edges belong to.
  • Others: in any decent classification there must be a miscellaneous category! Some algorithms do not really follow a particular definition, whether because they just add features to other community discovery algorithms or because they let the user define their communities and then try to find them.

And now just a shortlist of readily available community discovery algorithms you can find on the Web:

That’s it! I hope I created a couple of new community discovery aficionados!

The Paradox of Social Controllability

“It’s a bit sad that some among the most brilliant minds of our generation are working tirelessly on strategies to increase clicks on online ads” popped up on my Facebook stream some days ago (I don’t remember who wrote it, so you are welcome to contact me to restore credit where credit is due 🙂 ). But the point still remains. I actually don’t find it that bad. Yes, it’s bad, but it could be worse. It reminds me of other “wrong” reasons to do incredible improvements in science and stuff. For example, war is responsible for many technology advancements. Even if the aim of online marketing is just to increase revenues, what it actually requires is to understand human psychology, behavior and social interactions. In practice, that’s philosophy of the human mind at its best: how does the brain work? How does a collection of brains work? What drives our behavior and needs?

When you put together many minds in the real world, you have to deal with complex networks. We are not connected with one another at random, and the eyes of our friends are the channel through which we observe the world. This fact is studied in complex network analysis, in the sub-branch of cascade behaviors. Cascade behaviors happen when a person in a social network decides to modify her behavior according to the behavior of the people she is connected to. As a consequence, there are some people in the network who are in a very particular position: given the people they know and their prominence among them, they can modify their behavior and they will modify their friends’ behavior and so on an so forth, changing forever how every node in the network behaves. And that’s the cascade. If you find a way to identify these prominent actors in the network, you can control the behavior of the entire system. Now you can see why there is a mountain of work about it. In the computer science approach, we have threshold models simulating the cascade for many starting nodes and thus identify the practical leaders (for example Jon Kleinberg’s work); in physics we have models, aiming at understanding the degree of controllability of complex systems (I’ll go with Laszlo Barabasi in this).


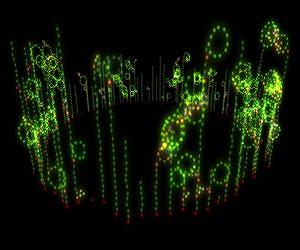
Visualization of network cascade, from my good friend Mauro Martino. The red dots at the bottom are the “drivers”, who influence the collection of green nodes they are attached to.

Genuinely curious about the topic, I started my own track of research on it. One thing that Diego Pennacchioli, Giulio Rossetti, Luca Pappalardo, Dino Pedreschi, Fosca Giannotti and me found curious is that everybody working on social prominence was looking at it from a monodimensional perspective. That means: the only thing they are interested in is how to maximize the number of nodes influenced by the leaders. The bigger this number, the better. All fun and games, but why? I can think about several scenarios where the final total number is not the most important thing. For example:

  • What if I want people to buy a product? The total number of people knowing about the product is nice, but I want them to be strongly committed, strongly enough to buy it.
  • What if I am actually looking to reach a particular person? Then I care how deeply my message can go through the network.
  • What if I just care about my friends? Then screw their friends (and everybody else), as long as I can influence a wide range of my direct connections!

toy
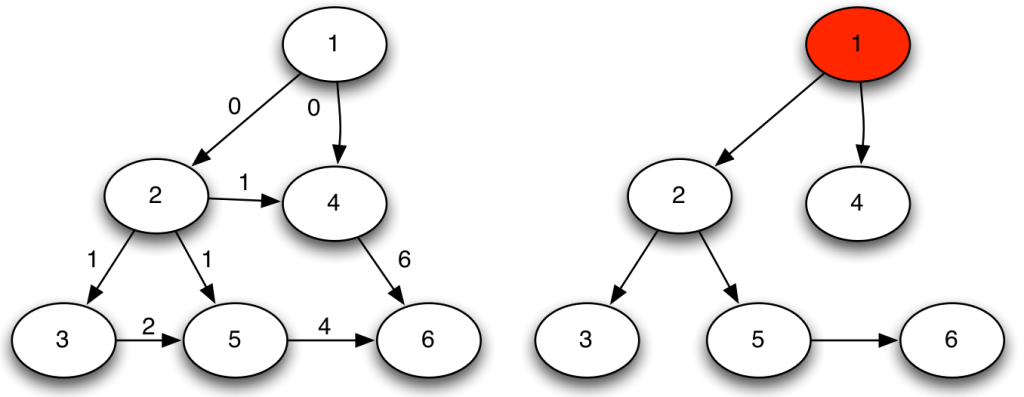
To calculate our measure we need to infer the diffusion trees. So from the left, where the number on each arrow gives you the action time of the node at the base of the arrow, we go to the right by selecting the lowest possible combination of arrows.

Strength, depth and width of social prominence. That’s why our paper is called “The Three Dimensions of Social Prominence” (check it out). Strength is how committed the people you influenced are to keep doing what you influenced them to do. Depth is how many degrees of separation (or, how far) the cascade of influence that you triggered can go. Width is simply the ratio of your friends that you are able to influence. By analyzing how much a user in Last.fm (a social website based on music) is able to influence her friends in listening to new artists, we found a collection of very interesting facts.

For example, it is well known that in social networks there are some nodes that are structurally very important. They are the central users, the ones that keep the network connected. Intuitively, they are the only way, or the easiest way, through which a signal (in our case social influence) can go from one part of the network to the other. Guess what: they can’t do it. We found a significant anti-correlation between centrality and width and depth. That is bad news, because those nodes are the ones in the only position with a theoretical ability of controlling the network and a practical inability in doing so. I like to call it “The Paradox of Social Controllability” (hence, the post title).

ds
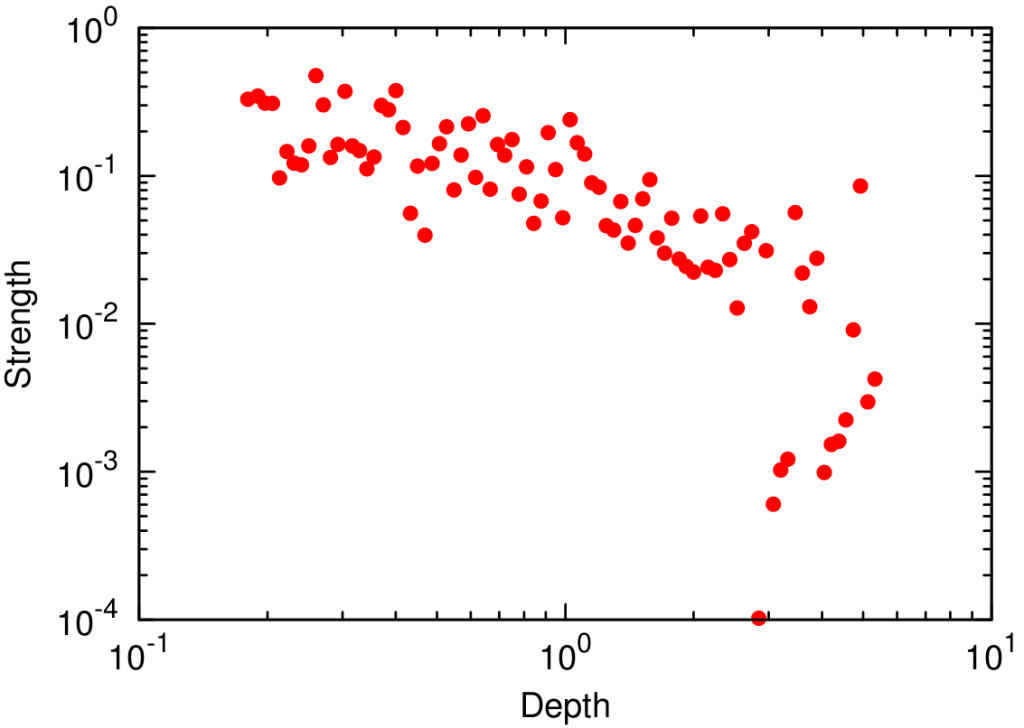
The anti-correlation between depth and strength.

Another piece of food for thought is the trade off between strength and depth. While width is unrelated to both, we found that if you want to go deeply into the network, then you can’t expect that the people you touch will be extremely committed to your message.

The third big thing is the distribution of connections per leader. We found that the leaders showing highest values of strength, depth and width were those who used Last.fm with average frequency. The highly connected and very active users (hubs, in network lingo) scored poorly, as we saw. So did the occasional users, the ones with just two or three connections (that is the majority of the system). The people who have control over the network are the mildly engaged. They are you, in practice: chances are that you are not a record label, nor a music fanatic, but just a person with her tastes and preferences. So you have control. Problem is, the control is scattered equally on the vast set of people like you.

To conclude, we saw what wonderful things network cascades are: they could empower us to do a lot of good. We also saw how there are theoretical results about the possibility of identifying people who can trigger them. But my unfortunate conclusion is about the paradox between theory and practice. Those who theoretically should, apparently can’t.

Personal vs Social Knowledge

Today I want to talk about jobs. Or, better, about finding a job. Sooner or later, this is a task that many people will have to perform and it is not usually a very enjoyable one. Writing a CV is mostly painful. You have to list all your skills, all the knowledge you have, what you have done in the past, the tasks you can perform. Everything to maximize your value to the eyes of the examiner, who is judge, jury and executioner of your working fate. But, after all, you can’t complain. You know the rules of the game. It is only fair, because the recruiter wants to see the best possible CV and the best possible CV is the one that includes the most relevant information: you have to stuff the maximum amount of skills in your body to maximize your value and it is the most valuable person the one who is going to be picked. Right?

Wrong. There’s one critical flaw to that reasoning, and that is time. Time is limited. You can’t spend too much time in stuffing knowledge into you, because there is too much knowledge out there and if you try to internalize everything you don’t have time to produce anything. This is not just my opinion. It is one of the cornerstones of widely accepted and useful theories, for example the division of labour. This is linked to the concept of “social knowledge“. Social knowledge is the collection of what people in society know. While personal knowledge is bounded by time, social knowledge is not, because many different brains work on it at the same time, making it grow beyond what any individual can grasp.

social-knowledge-broker

If you want to have 100 people to make cars, you don’t teach each one of them to make a car from scratch and then you watch them making 100 cars at the same time. Each guy will assemble one part. And he’ll be awesome at that particular part. This applies not only to manufacturing. How many times in your working life you found yourself struck with a problem, not exactly in your knowledge domain, and you solved it by simply asking someone about it? In my case, many. Think about how many times you Google something. That’s accessing the social knowledge of humanity. That is one of the reasons why, for example, the social return of education exceeds the private return.

The way you access social knowledge also changes the usefulness of it. It is better if a friend takes time to explain things to you than if you have to read an answer in Quora, that is also related only to some extent to your specific problem. Because tacit knowledge needs a broker to make it explicit and understandable. So it is better to have knowledgeable friends in many fields, or: your social network matters for your qualifications, because it’s the principal medium you use to get explicit knowledge from the tacit social knowledge.

social-network

So it seems like we are onto an interesting problem. On one hand, I hope to have convinced you that social knowledge is an important component of someone’s value; on the other hand that creates more questions than answers. How do we evaluate a person for a job? How do we measure the social knowledge she has access to? Well, if you know me you know what’s going to happen. A network algorithm, of course! Precisely, an algorithm with a flavor of Philip K. Dick in its name: UBIK, or “U know Because I Know”. This algorithm has been created and developed with the help of Giulio Rossetti, Diego Pennacchioli and Damiano Ceccarelli and has resulted in a paper published in the ASONAM 2013 conference that will take place later this month. Also, the code of UBIK is available for use.

Here’s how UBIK works. First, you have to start by collecting information about the social connections of people. It’s even better if you can find multiple types of connections from multiple sources, because the channel through which knowledge passes influences the quality of that knowledge. Second, for each person you have to collect their CV. Personal knowledge is still important. Once you have these pieces of information, UBIK can unweave its magic.

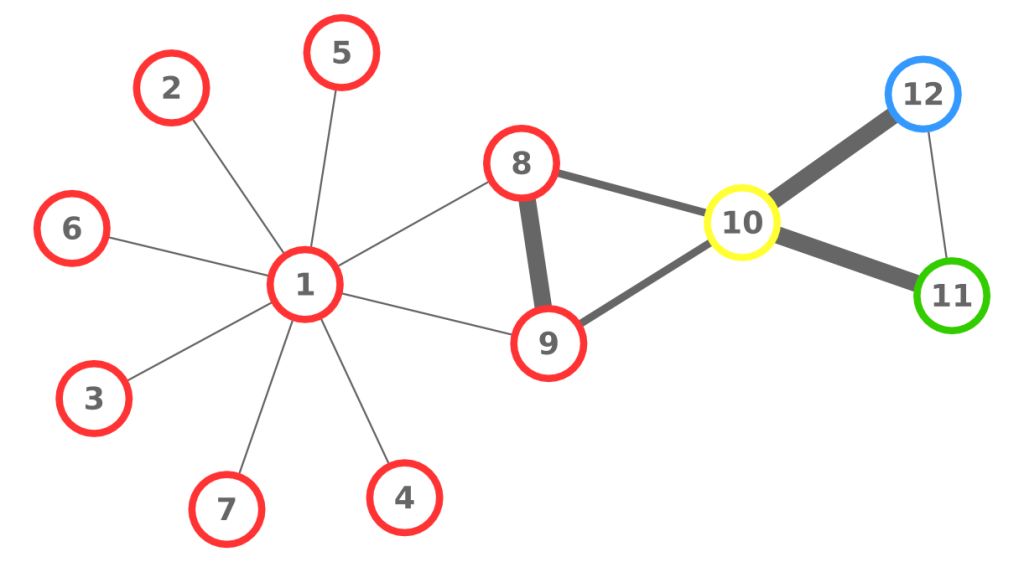
ubiktoy

Let’s look at a simple example. The above picture can be considered a network of people: each node is a person, each person is connected to the people she knows, her color represents the skill in which she is specialized, and the width of the link is the strength of the connection (important: UBIK works with qualities of links, not strengths, but for the sake of simplicity in this example we use the latter). The consequence of our theory is that the skills of each person are transferred through the links of the network. Also, a direct connection is stronger than a connection through another node. For example, node 8 passes her skills more efficiently to 1 than node 10 does.

So, at the first iteration, UBIK passes the skills of each node to its neighbors. Node 1 gets a lot of red skill, node 10 gets all kinds of skills. It is a percolation process. At each iteration, UBIK keeps passing the entire set of updated skills, with an increasing penalty due to the social distance. I won’t bother you with the equations. Just know that, at some point, the penalty is so high that the algorithm stops.  The skill transfer happens proportionally to the strength of the links connecting the nodes. As a result, node 10 is super valuable, because she has access to the knowledge about all skills in the network, while for example node 1 will be a uber-specialist of the red skill. By just looking at their CV, it would be impossible to extract this information.

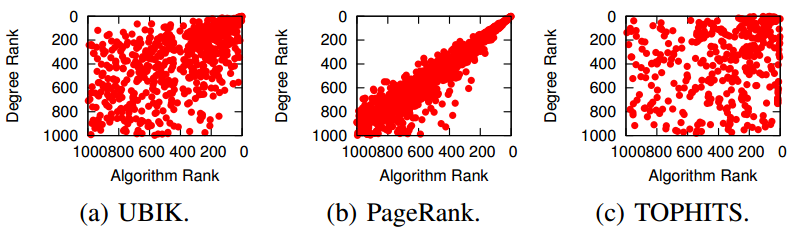
ubikplots

Some of you familiar with network analysis may have some bells ringing in their heads. “This is node ranking!” Well, yes. “So just use PageRank!” “Or HITS!” “Why do we need UBIK?” Well, for a number of reasons. First, UBIK handles multiple link types and multiple skills at the same time: (variants of) PageRank and HITS can do one or the other, but not so many can do it simultaneously yielding effective results. Second, PageRank and HITS have flaws. PageRank correlates with degree (the number of connections of a node) and centrality measures: see the above picture where we confront the rankings of the algorithms with the degree rank. HITS has similar flaws related to the nodes’ tendency of cluster in communities.

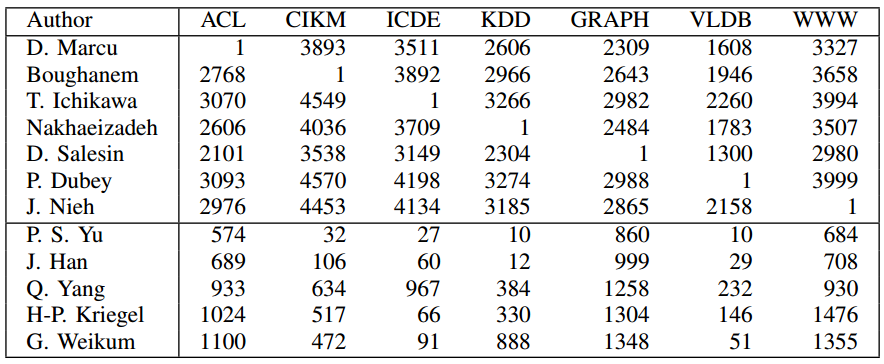
Moreover, when we applied the algorithms to network of researchers, UBIK was most likely to rank them in the same way as measures independent from networks such as the H-Index. This shows that UBIK may be more useful than other network ranking techniques when these independent evaluation criteria are not available. The beauty of UBIK consists in multiple rankings. Below I report some rankings of researchers in Computer Science. Each number is the rank that UBIK gave to the researcher in a particular conference. Each conference is a different ranking that UBIK is able to distinguish. We are able to spot the specialists of many computer science conferences, highlighting their prominence in one community and low ranking in others. Also, we report the rankings in these conferences for the most prominent general authors, showing that they rank on average well in many different venues, but they are not really specialists.

ubiktable

And that’s why you should give UBIK a chance.

NetSci 2013 Report

As I mentioned a couple of months ago, during the first week of June the NetSci conference took place. NetSci is the main venue that brings together all researchers interested and involved in network science. It has always been a gigantic opportunity to put you in contact with the big shots in network analysis and an excellent playground for very interesting discussions. This year was no different.

Of course, for me the most important part of it was the very first day, when the satellite on multiple networks (organized by myself together with Matteo Magnani, Dino Pedreschi, Luca Rossi, Guido Caldarelli and Przemyslaw Kazienko) happened. As I wrote more than once in the past, multiple networks are networks in which the nodes may be connected with different kinds of interactions (friendship, collaboration, and so on).

It was an extremely interesting event; a first step to bring together many researchers working on the topic of multiple networks, most of whom hadn’t spoken to each other up until then. And when I say it was a smooth and successful operation, you don’t have to take my word for it. We have proof of a room full of brilliant minds taking up all the available spots… and beyond:

The talks were very impressive:

  • We learnt how to measure eigenvector centrality on multiple networks (and you can too);
  • We learnt how to extend basic measures from regular complex networks to multiple networks (and you can too);
  • We learnt how to mine network with heterogeneous information on nodes and edges (and you can too);
  • We learnt how to detect communities on multiple networks (and you can too);
  • We learnt how to infer the latent structure of inter-related networks (and you can too);
  • We learnt how a random walker behaves on dynamic networks (and you can too);
  • We learnt about the structure and dynamics of multiple networks (and you can too);
  • And we learnt how the properties of multiple networks arise when adding one network at a time (and you can too).

But NetSci, of course, was much more than just this satellite. Another event you absolutely didn’t want to miss there was the Arts, Humanities and Complex Networks Symposium, organized by Max Schich and Isabel Meirelles.

They are both great guys, with a gigantic knowledge about art and design. For example, they picked up a great reference for the logo of their symposium, namely one of the most known infographics made about visual arts, by Alfred Barr:

And besides the usual great lineup of talks (from the Wikidata project to a very cool movie ranking multiple network algorithm) you can learn surprising stuff about basically everything. My favorite: the observation of one of the speakers about the above visualization itself. Apparently, he was the first to realize that there is a bull up there (hint: Cubism lays in between the bull’s horns). As Max then puts it:

Then… the rest of the conference. It is impossible to even give a close idea of the overload of ideas and flashes of genius that populated the venue for those three days. I’ll work around the problem and cheat by giving you a laundry list of (a very tight subset of) the things that most impressed me during the conference:

  • The excellent invited talk by Shlomo Havlin about interdependent networks (networks which depend on each other to function, much like a computer network controlling the electric grid). This interests me because he claims that interdependent networks are a more general case of multiple networks (although I personally have an inkling that perhaps they can be reduced to the same model);
  • The usual spectacular presentation style of my friend Cesàr Hidalgo, who this time talked about a complex system showing a nested structure: namely, the cultural exports of different countries;
  • A really great contributed talk by Esteban Moro, which in my opinion could have been a keynote speech as well. Dr. Moro highlighted how people have a trade-off between social capacity (how many relationships we can keep alive) and social activity (how many new people we can meet). As a consequence, different social strategies arise;
  • A brilliant mathematical formulation of a network problem by Jure Leskovec, that, in my opinion, could be the final word about the problem itself. And it resembles the formal mathematical formulation of the same algorithmic idea behind my DEMON;
  • And the hilarious ignite talks, 5 minutes and 20 slides for each speaker. There was no possibility of interacting, with the presentation automatically jumping to the next slide every 15 seconds. Next year I definitely want to try to do one too.

And, of course, many other things. But you get the idea: blog posts about it are boring, you really have to experience it yourself.

Multidimensional Networks @ NetSci!

This month, I am interrupting the sequence of posts discussing my papers for a shameless self-promotion – after all, this entire website is shameless self-promotion, so I don’t see a problem in what I’m doing. Some months ago, I discussed my work on multidimensional networks, networks that include different kinds of relations at the same time. The whole point of the post was that these are different animals than traditional complex networks, and thus they require new tools and a new mindset.

So I asked myself: “What is the best way to create this new sensibility in the network community?”. I also asked a bunch of other great people, in no particular order: Matteo Magnani, Luca Rossi, Dino Pedreschi, Guido Caldarelli and Przemyslaw Kazienko. The result was the topic of today’s post: a symposium in the 2013 edition of the NetSci conference!

NetSci is a great venue for network people. From their website:

“The conference focuses on interdisciplinary research on networks from various disciplines such as economy, biology, medicine, or sociology, and aims to bring new network analytic methods from physics, computer science, math, or statistics to the attention of a large and diverse audience.”

This year, NetSci will take place in Copenhagen and you should check out a number of reasons for attending. One of those reasons is our symposium, called “Multiple Network Modeling, Analysis and Mining“. You can check important information about attending the symposium in the official event webpage: http://multiplenetworks.netsci2013.net/. Here are the three main highlights:

  • It is an excellent occasion to learn more about multidimensional networks, a model that can help understand the complex interplay between the different relationships we establish every day (friendship, collaboration, club membership, …), better than everything else has been done before;
  • We still have to finalize our speaker list, but it will be of very high quality and will include Jiawei Han, Lei Tang, Renaud Lambiotte and others;
  • Symposium attendance is free! And there will be free food! Woo-hoo! Just sign up in the official Google Doc.

Don’t take my word on the first point and check out the publications we refer to in our webpage. Here, following the above mentioned shameless self-promotion, I’ll list the papers on the subject written by yours truly:

If you find all of this interesting, I definitely hope to see you in Copenhagen this June!

Complexity Squared

I decided to give to this blog post an obscure title because today I want to talk about something that in complex network analysis goes under many names, so I did not want to favor any of them. What I am talking about are networks with multiple types of relations in them, the main subject of my PhD Thesis and of a recent article that I published in the World Wide Web Journal. These structures are putting more complexity on top of complex networks, therefore they are complex network squared: hence the fancy blog title.

These networks are referred to in the literature with the following terms:

  • Multidimensional (the term that I use in my thesis);
  • Multirelational;
  • Layered;
  • Interdependent;
  • Multisliced;
  • Multilevel;

and so on and so forth. All these terms refer to the same theoretical object, that is also implemented in many ways. I’ll mention some of them just to sound like the guardian of an obscure cult: labeled multigraphs, hypergraphs, mesostructures and coupling edges.

Despite the confusion that I tried to create with the first paragraphs, the general idea of this line of research is brutally simple: in our everyday life we are not part of only one network. It may look like we are, but when we start thinking harder about our relationships, we realize that we know the people we know for different reasons. This idea is the one behind the fact that every person can belong to different “communities” at the same time, which I already discussed in these pages. But it is deeper than that. It does not only require the more sophisticated, but still traditional, community discovery algorithm that I described in that blog post. It requires a whole new model and mindset.

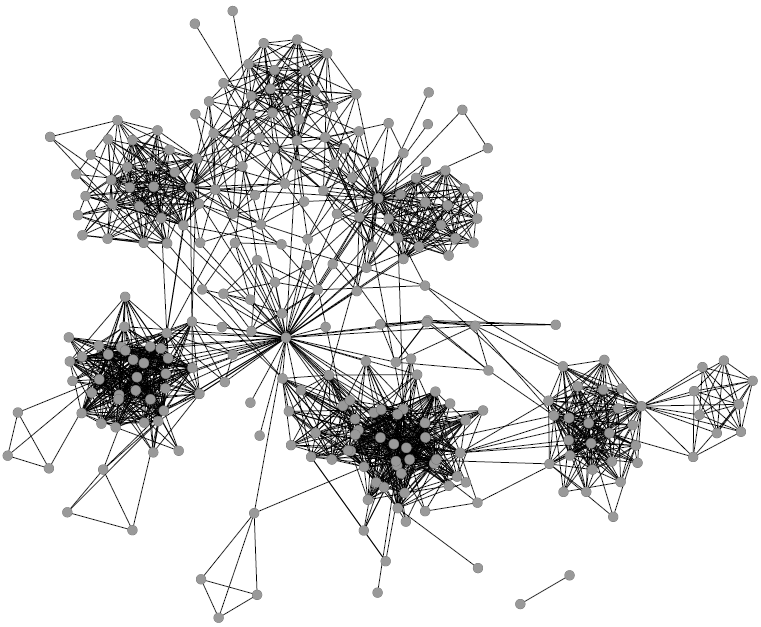
Before multidimensional networks (forgive me if for clarity I’ll use my term for these structures) the classical complex network analyst would just assume that a single relation represents a particular phenomenon and nothing else can be said about it. Allow me to recycle this picture about my Facebook friends:

Intuitively this looks nice, as we can find communities and central nodes. But is this picture really telling us everything about my Facebook friends? What about a higher order of aggregation among them? What about not only their friendship links but also their common interests? The multidimensional network analyst throws a bunch of new connections on top of it and she tells you: “There’s something more”. In this case:

A visualization that is not nearly as elegant as the previous one, I give you that, but nevertheless it is useful to understand a higher level aggregation of my Facebook friends. On top of the connections between friends, we added edges connecting people if they are part of the same group or if they like the same stuff on Facebook. The two gigantic hairballs are composed by people who are in the same location: there is the cluster of people living in Italy, the one of people living in the US, and connections between them from people travelling between the two countries. So, we saw that adding different types of relations uncovers structural properties that none of the relations by itself would reveal.

I’ll give you another example of a cool real world effect of multidimensional networks. This is not from a work of mine, but it is from the Nature paper “Catastrophic cascade of failures in interdependent networks” by  Sergey V. Buldyrev, Roni Parshani, Gerald Paul, H. Eugene Stanley and Shlomo Havlin. Suppose you have a power grid: what happens if one plant is subject to a failure? The classical complex network analyst tells you that we could not care less: the power grid is a scale free network, in which the majority of plants are only connected to a couple other plants. So, a random failure of one plant does not affect the rest of the network too much, unless we are extremely unlucky and we lose a power hub (but that’s really rare, and the classical network guy is an incurable optimist).

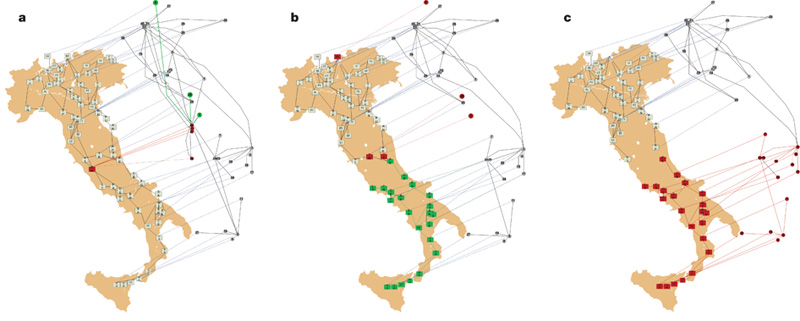
A multidimensional network scientist, instead, is way more careful. Why? Because he knows that the power grid network is not independent from everything else, but it is plugged into another network. For example, in a computer network that regulates its functioning. When a power plant goes down, a set of computers cannot work anymore. And what happen to the plants that are connected to those computers? They fail too, triggering another computer failure and God helps us all. It is theoretically proven that two different scale free relations, dependent on each other, are much much much more fragile than a single scale free network. This actually happened in Italy (where else?) and the following is a depiction from Buldyrev et al’s paper:

In the first Italy we see one plant going down (in red on the map) taking with it the computers it supplies with energy (in the flying network). This triggers a couple more failures in the second picture that eventually, in the third picture, completely destroy the power supply chain of southern Italy.

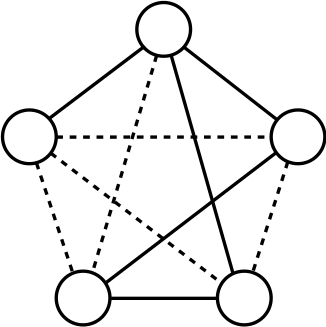
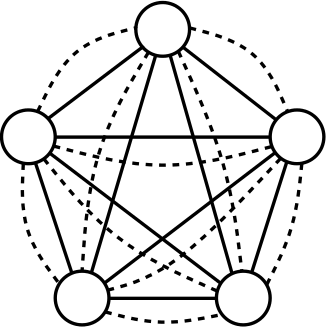
So far I gave you the idea that multidimensional networks are not exactly the same animal as classical complex networks. To give you a taste of how to prove this, I’ll spare you the super complicated equations of interdependent network percolation present in the Nature paper. I’ll instead provide another example from community discovery. As I said in my previous post, community discovery is loosely defined as the problem of grouping nodes in a network that are “densely connected”. Naturally, when we deal with multidimensional networks, the “densely connected” has to be changed into “multidimensionally densely connected”. Why is this challenging? Here I’ll give you an intuition and I promise that in the future I’ll come back with more details. For now, it is sufficient to use two pictures. Here’s the first:

Here we assume that we have two different dimensions and they are represented with solid or dashed edges. Is this set of nodes multidimensionally dense? Of course: everybody is connected with everybody and all dimensions of the network are equally represented. Now consider another situation:

Is this set of nodes multidimensionally dense? Of course: everybody is connected with everybody and all dimensions of the network are equally represented. But the two examples are very different. That’s funny: we just discovered that, in multidimensional networks, density is an ambiguous concept.

And, as conclusion, I’ll add some multidimensional flavor to another classical network problem: link prediction. Link prediction aims at predicting your next Facebook friend. The above mentioned multidimensional network scientist steps in and says: “But why only your next Facebook friend? Why not your next virtual acquaintance tout-court?”. He means that all your social media connections and their different types play a role in determining when and where you’ll connect with somebody. This is exactly what multidimensional link prediction is, and how to do this is a complex problem that currently remains unsolved. But the multidimensional network guy loves complex problems as much as he loves complex words.

The Product Space and Country Prosperity

As reported in different parts of this website, the group I am currently working in is called “Center for International Development”. The mission of this group, in the words of its head Ricardo Hausmann, is quite trivial and unambitious: to eradicate poverty from the world. Knowing how to do it is far from easy and there are different schools of thought about it. The one that Hausmann chose starts with understanding how production and economic growth work, i.e. why some industries are successful in a country and not in another.

To address this question, Hausmann (together with César A. Hidalgo, Bailey Klinger and Albert-Laslo Barabasi) developed the Product Space. The original idea has been published in this paper in 2007, far before I joined the group, but my (overestimated) expertise was heavily exploited to generate its current implementation (the Atlas of Economic Complexity, a book freely available in electronic format). For this reason I feel no shame in writing a post about it in this blog (and to share the Product Space itself in my Dataset page).

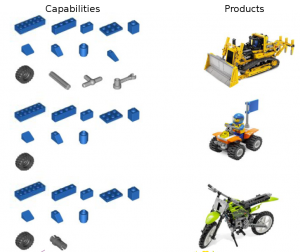
The fundamental assumption of the Product Space is the following: countries are able to have a comparative advantage in exporting a given product because they have the capabilities to export it. In abstract, it means: “I do this, because I can“. Quite reasonable. In pictures, with the awesome “A capability is a piece of LEGO” metaphor created by Hidalgo:

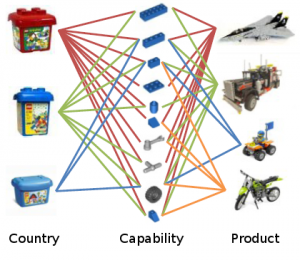
From this assumption, it follows that if a country can export two different products, it is because it has the capabilities to export both. Also this step is quite easy. The conclusion is immediate: a country’s development success is lead by its capabilities. The more capabilities the country has (meaning that its LEGO box is big and it contains a lot of pieces), the more capabilities it will be able to acquire, the faster it will grow.

There is a small problem with this conclusion: we can’t observe the capabilities. Of course, if we could then they would be blatantly obvious, so every country could employ its growth strategy based on them. (There is actually another problem: capabilities are tacit knowledge, as Nonaka and Takeuchi would say, so you really can’t teach them, but we will come to this problem later)

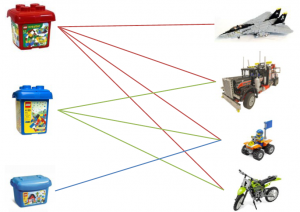
What we can observe is simply which countries export what:

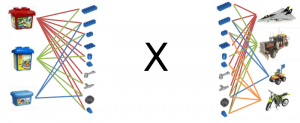
But remember: if two products are exported by the same country, then there may be common capabilities needed for their productions; while if two countries export the same products, then they share at least part of the same capabilities. In mathematical terms, it means that the observed country export picture is actually the multiplication of the two halves of the second picture of the post, or:

This is nice because it means that we can collapse the country-product relationships into product-product relationships and then mapping which product is related to which other product, because it requires the same capabilities. The advice for countries is then: if you are exporting product x, then you are likely to have most of the capabilities to export all the products that are connected to x. And this is how the Product Space was born, a single picture expressing all these relationships:

(click on the picture for a higher resolution, or just browse the Atlas website, that is also dynamic).

In the picture the nodes are colored according to the community they belong to (for more information about communities, see a previous post). The communities make sense because they group products that intuitively require the same extended set of capabilities: in cyan we have the electronic products, light blue is machinery, green is garments and so on and so forth.

Is the structure of the Product Space telling us something reliable? Yes, countries are way more likely to start export products that are close, in the Product Space, to the products they already export. Also, it is important to know where the export products of a country are in the Product Space. The more present a country is in the denser cores of the Product Space, the more complex it is said to be. This measure of complexity is a better predictor of GDP growth than classical measures used in political economy like average years of schooling.

Is the structure of the Product Space telling us something interesting? Hell yeah, although it’s not nice to hear. The Product Space has communities, so if you export a product belonging to a community then you have a lot of options to expand inside the community. However, many products are outside the communities, and they are very weakly connected with the rest, often through long chains. The meaning? If you are only exporting those products, you are doomed to not grow, because there is no way that you’ll suddenly start exporting products of a community from nothing (because this would require tacit knowledge that you cannot learn and is not close to what you know). And guess what products the poorest countries are currently exporting.

To conclude, a couple of pictures to provide one proof of the reasoning above. In 1970, Peru had more average years of schooling, more land and twice the GDP per capita of South Korea. Traditional political economy would say that Peru was strong and there was no way that South Korea could catch up. Where South Korea is today is evident. What was the difference between the two countries in terms of Product Space?

(again, click for higher resolution. The black square border indicates which products the country is exporting). There is not a lot of difference in quantities (and this explains why South Korea was poorer). However, South Korea had those two or three products in a very valuable position, while Peru had only products in the branches: a long way to the core. In 2003, this was the result:

Peru is still mainly on the edges, South Korea occupies the center. And that’s all.